NeurIPS 2025 Main Conference, Poster
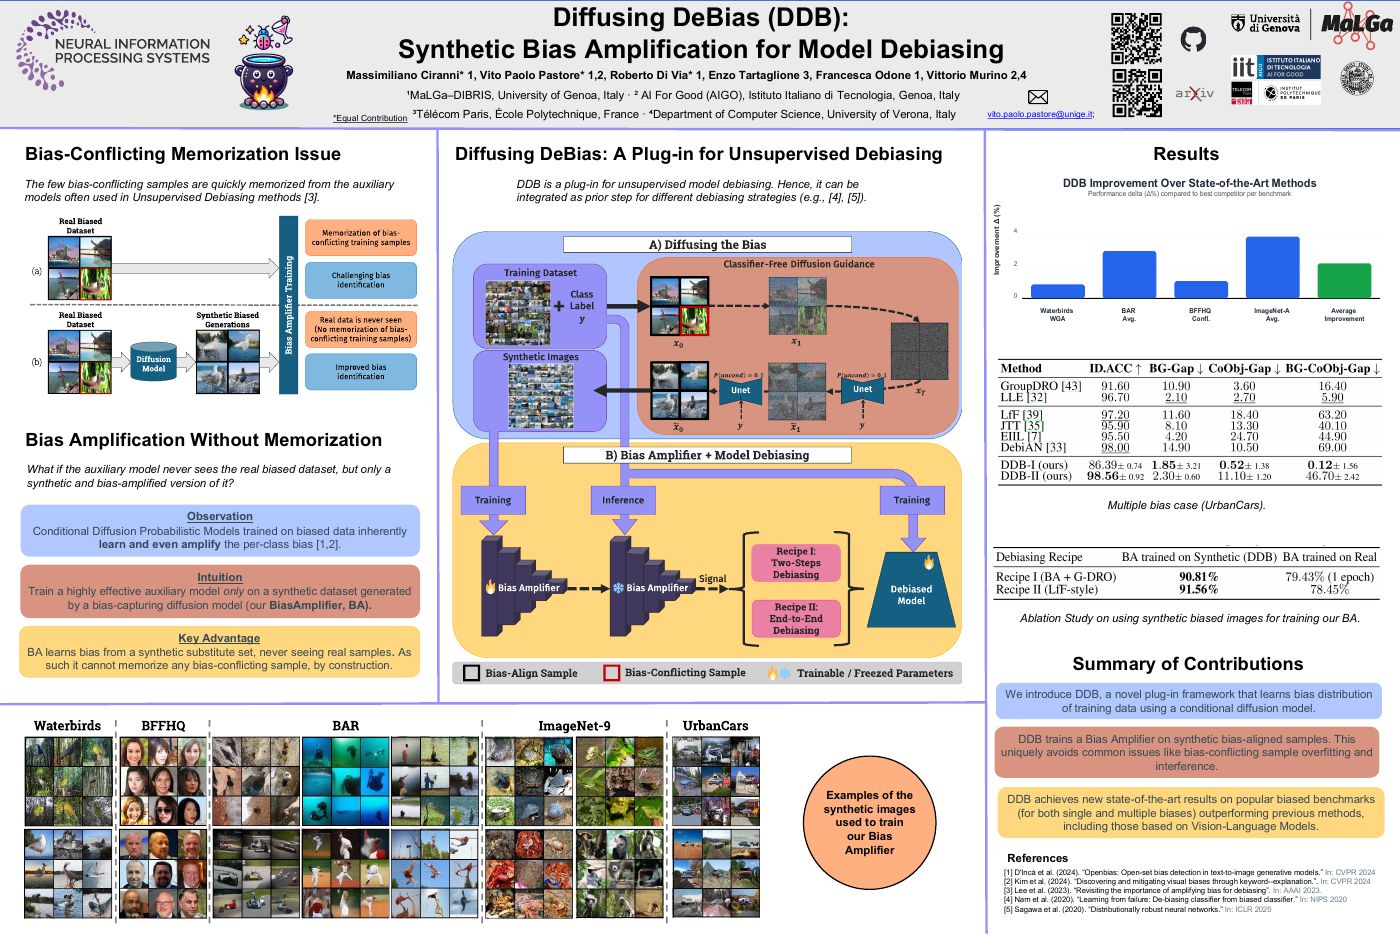
Diffusing DeBias Synthetic Bias Amplification for Model Debiasing
1MaLGa-DIBRIS, University of Genoa, Italy 2AI for Good (AIGO), Istituto Italiano di Tecnologia, Genova, Italy 3Telecom-Paris / École Polytechnique, France 4Dept. of Computer Science, University of Verona, Italy
Abstract
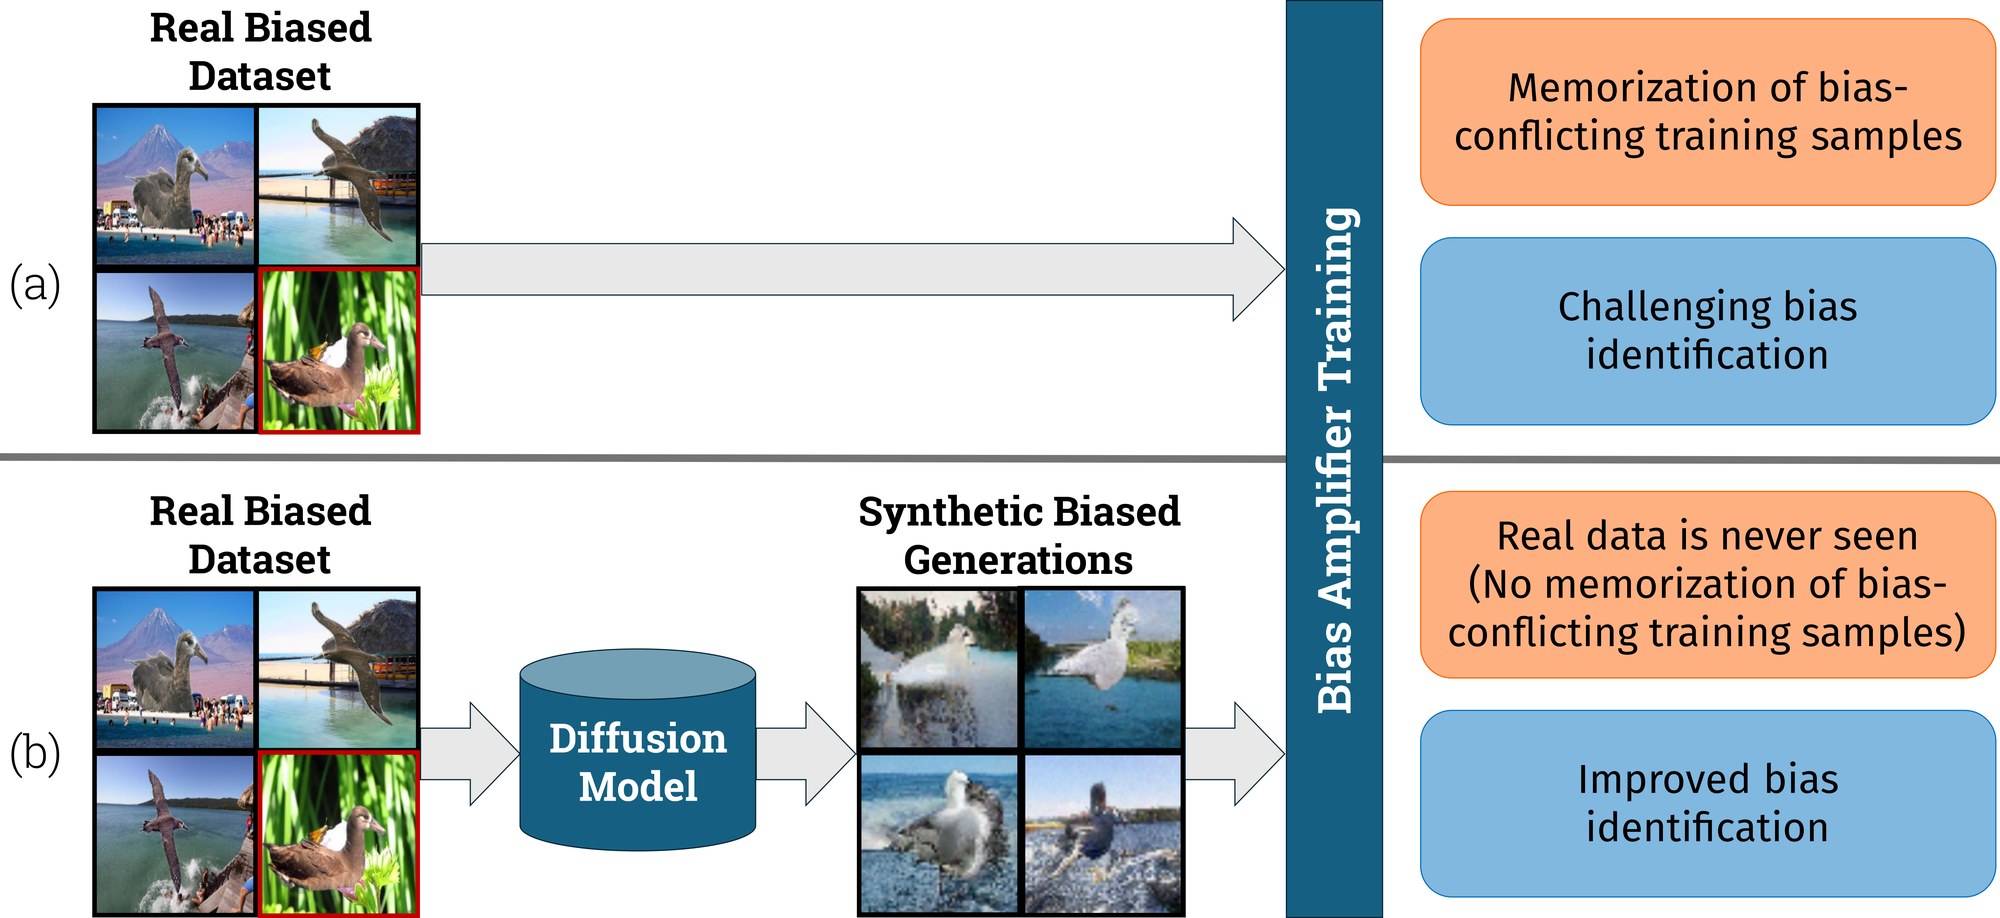
The effectiveness of deep learning models in classification tasks is often challenged by the quality and quantity of training data whenever they are affected by strong spurious correlations between specific attributes and target labels. This results in a form of bias affecting training data, which typically leads to unrecoverable weak generalization in prediction. This paper addresses this problem by leveraging bias amplification with generated synthetic data only: we introduce Diffusing DeBias (DDB), a novel approach acting as a plug-in for common methods of unsupervised model debiasing, exploiting the inherent bias-learning tendency of diffusion models in data generation. Specifically, our approach adopts conditional diffusion models to generate synthetic bias-aligned images, which fully replace the original training set for learning an effective bias amplifier model to be subsequently incorporated into an end-to-end and a two-step unsupervised debiasing approach. By tackling the fundamental issue of bias-conflicting training samples’ memorization in learning auxiliary models, typical of this type of technique, our proposed method outperforms the current state-of-the-art in multiple benchmark datasets, demonstrating its potential as a versatile and effective tool for tackling bias in deep learning models. Code is available at https://github.com/Malga-Vision/DiffusingDeBias.
Key contributions
Synthetic bias amplification
Conditional diffusion models learn the per-class bias-aligned distributions of biased datasets with unknown bias information, and their synthetic bias-aligned images train a robust Bias Amplifier
Memorization-free Bias Amplifier
By training exclusively on synthetic data, we avoid memorizing bias-conflicting real samples, leading to better generalization
Plug-and-play framework
DDB can be integrated into various debiasing recipes (both two-step and end-to-end approaches)
State-of-the-art results
On popular benchmarks with single or multiple biases, without degrading performance on unbiased data
Comprehensive analysis
Extensive ablations studying CFG scale, synthetic data quantity, and comparison with real-data training
Method overview
Key innovation: synthetic bias amplification
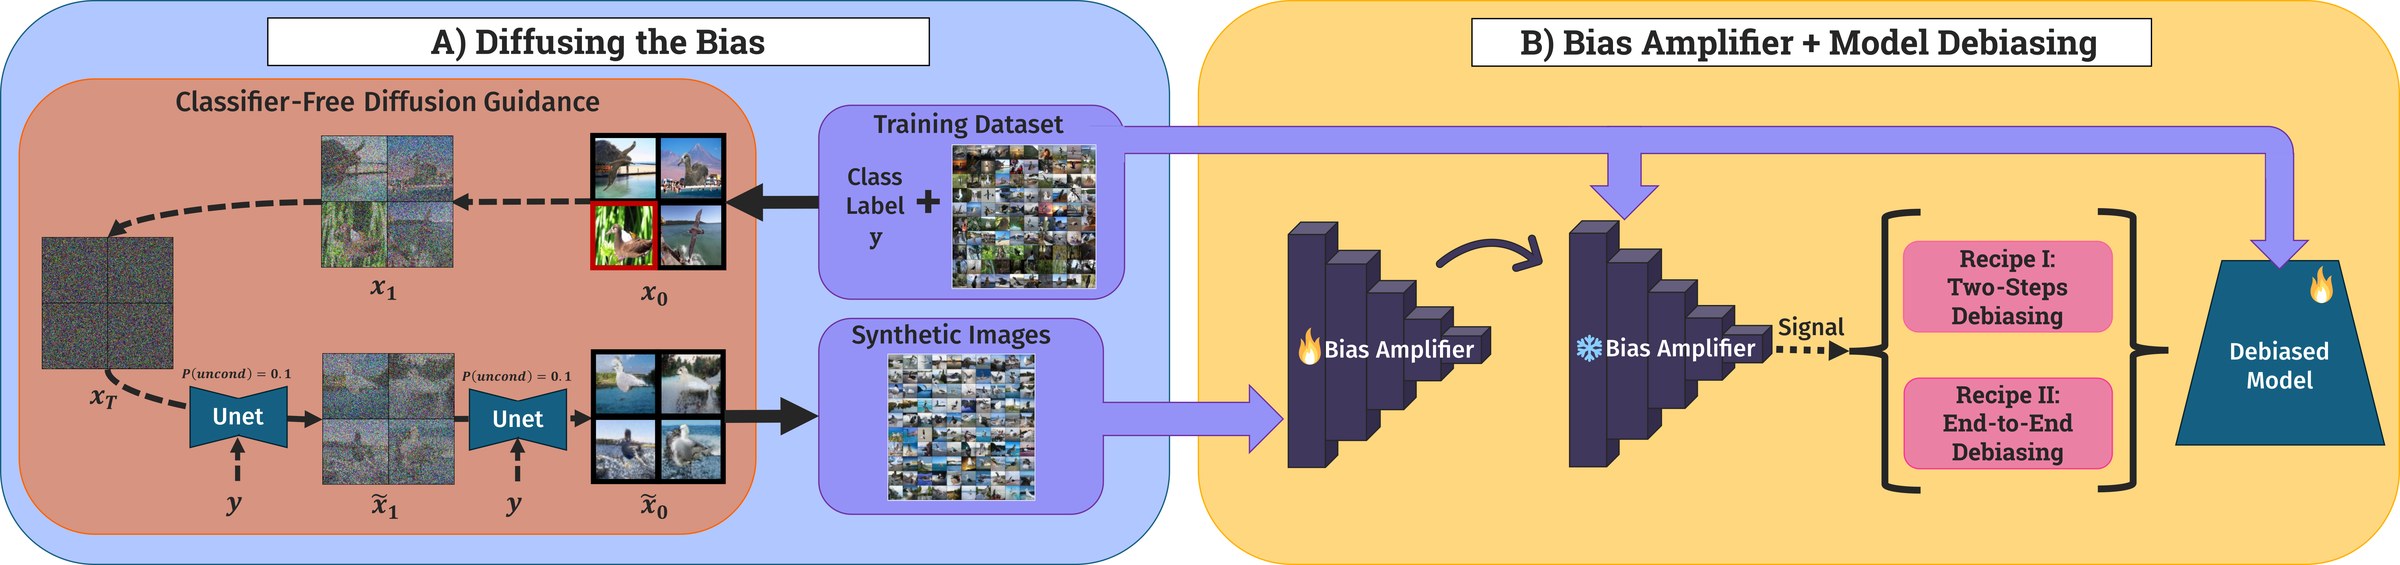
The core idea of DDB is to avoid training the Bias Amplifier on real data. Traditional approaches train bias models on the real training set, which leads to memorization of bias-conflicting samples—the very samples we want to upweight during debiasing. Instead, DDB:
- Trains a class-conditional diffusion model on the biased training dataset
- Generates synthetic bias-aligned images with classifier-free guidance (CFG): trained on data with strong spurious correlations, the diffusion model learns and amplifies the per-class biased distribution (guidance strength w = 1, the best value in the ablation)
- Trains the Bias Amplifier exclusively on synthetic data, ensuring it learns to recognize bias patterns without memorizing real bias-conflicting examples
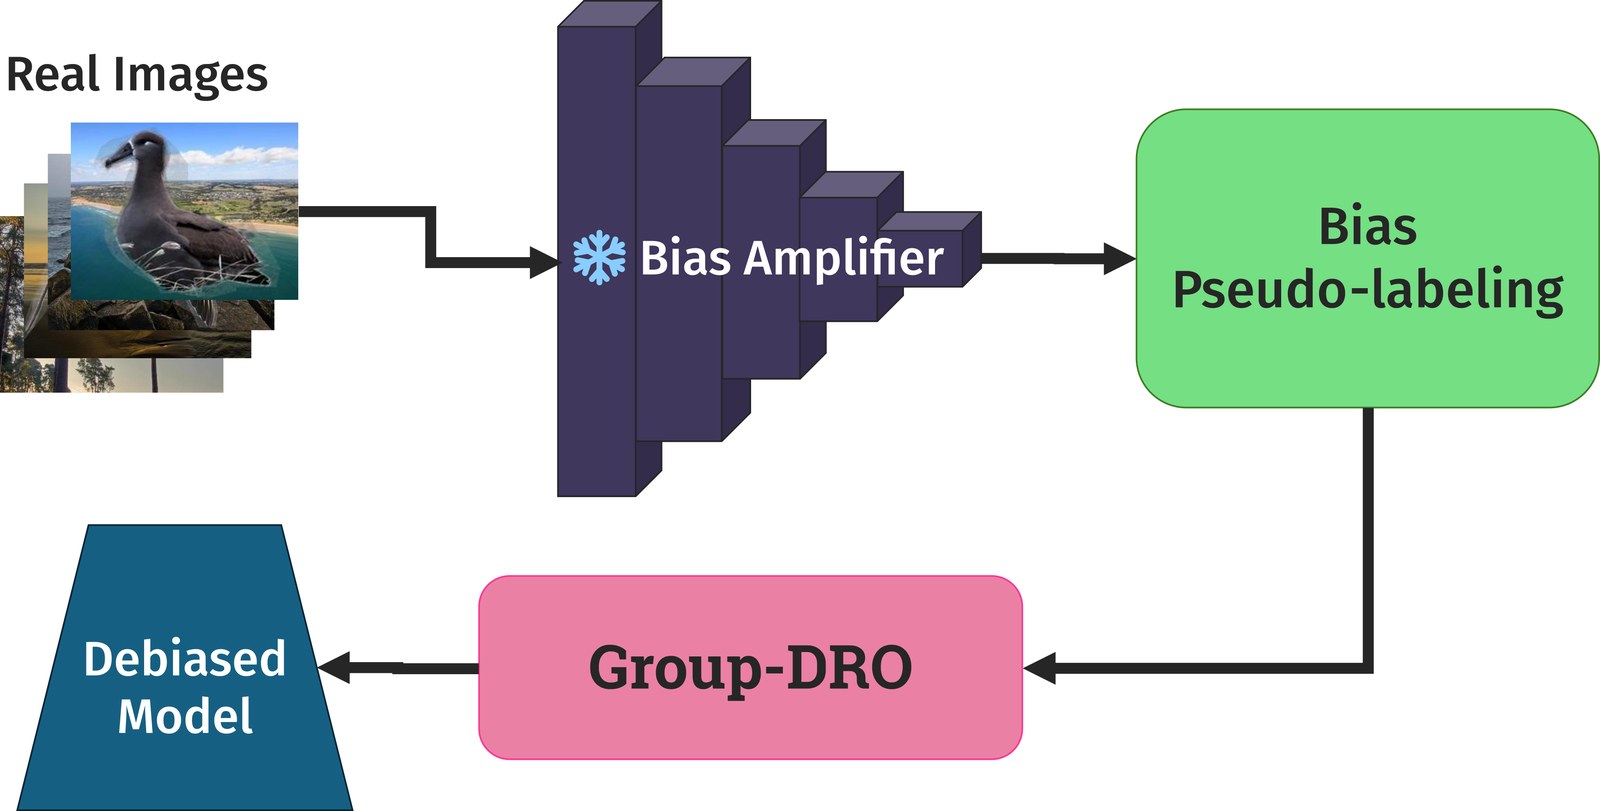
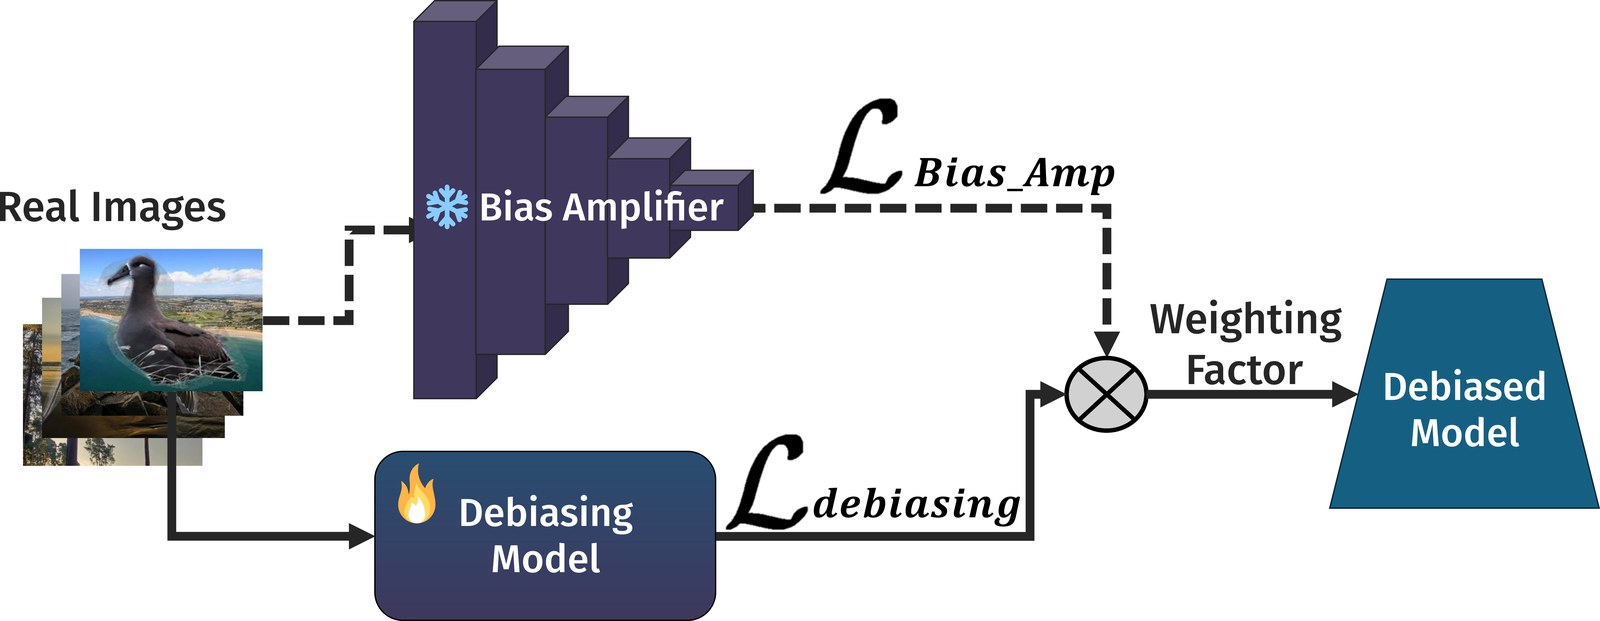
- Integrates the BA into debiasing recipes (Recipe I: two-step, bias pseudo-labels for GroupDRO; Recipe II: end-to-end, LfF-style reweighting with the frozen BA)
Why this works
Since the Bias Amplifier is trained on purely synthetic bias-aligned data and does not see the original training set at all, bias-conflicting sample overfitting and interference are avoided by construction. Auxiliary models trained on real data instead tend to memorize the few bias-conflicting samples within very few epochs, failing to provide different learning signals for bias-aligned and bias-conflicting samples.
Synthetic bias-aligned samples
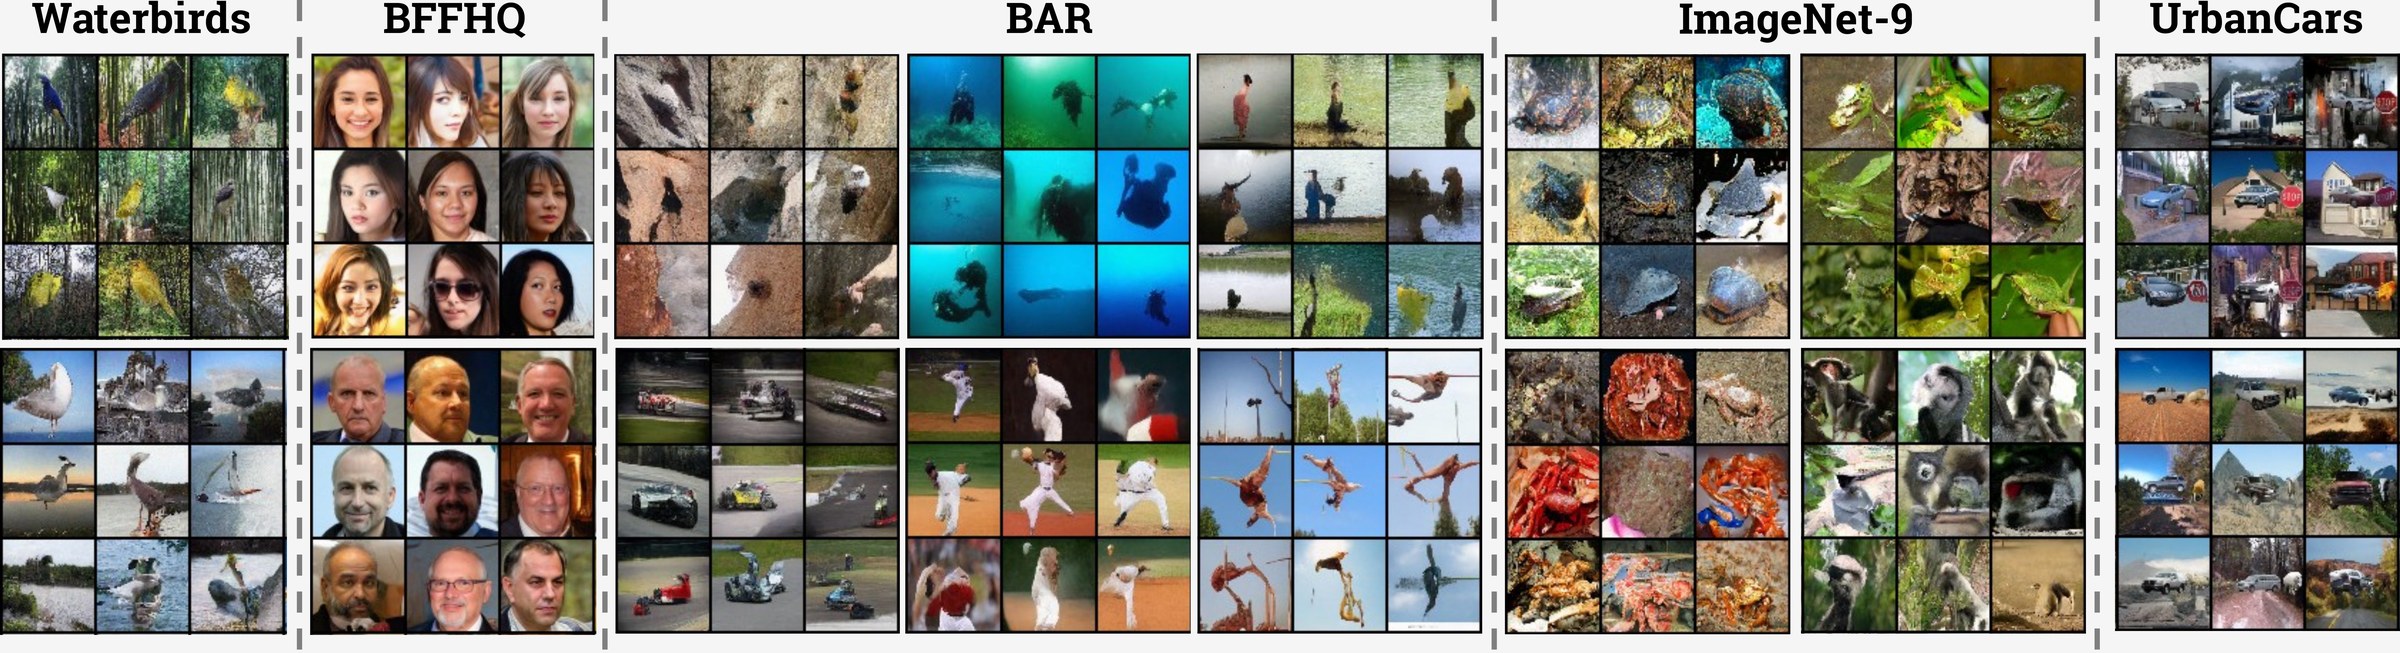
The generated samples maintain good fidelity and capture the typical bias patterns of each training set per class. Three independent annotators verified the presence of the bias in each synthetic sample: the average bias-aligned proportion is 98.35% for Waterbirds, 99.20% for BAR and 99.70% for BFFHQ, all higher than the known proportions of bias in the original datasets. On Waterbirds, BLIP-2 captions of the generated images show, together with the object class (bird), frequent bias-attribute words (land, water).
Integration with debiasing recipes
Recipe I: two-step debiasing
Recipe II: end-to-end debiasing
Recipe I (Two-Step): The BA, trained on synthetic data, is run in inference on the real training set. Samples it misclassifies, and whose loss is above the mean training loss plus γ standard deviations, are marked as bias-conflicting; the others as bias-aligned. These bias pseudo-labels are used as group information for GroupDRO, which trains the debiased target model.
Recipe II (End-to-End): Following the Learning from Failure (LfF) scheme, the GCE-trained biased model is replaced with the BA, which is frozen and only used in inference to compute its loss on each real training sample. The target model's CE loss is reweighted by r = LBA / (Ldebiasing + LBA), which should be low for bias-aligned and high for bias-conflicting samples.
Experimental results
We evaluate DDB on five popular biased benchmarks with different types of spurious correlations:
- Waterbirds: bird species correlated with backgrounds (water vs. land), ρ = 0.950
- BFFHQ: face age classification (young vs. old) with gender bias, ρ = 0.995
- BAR: six actions associated with stereotypical contexts, no bias annotations
- ImageNet-9/A: training on ImageNet-9 (textural and shape biases), testing on ImageNet-A
- UrbanCars: urban vs. country cars with two shortcuts, background and co-occurring objects
Main results: Waterbirds and BAR
Main results: BFFHQ and ImageNet-9/A
Main results: UrbanCars (multiple shortcuts)
Table 3. Comparison on the UrbanCars biased dataset. ID.ACC is in-distribution accuracy (the higher, the better); the other three metrics show the accuracy gap between each minority group and ID.ACC (the lower, the better). GroupDRO and LLE are listed first as they rely on bias information.
| Method | ID.ACC ↑ | BG-Gap ↓ | CoObj-Gap ↓ | BG-CoObj-Gap ↓ |
|---|---|---|---|---|
| GroupDRO | 91.60 | 10.90 | 3.60 | 16.40 |
| LLE | 96.70 | 2.10 | 2.70 | 5.90 |
| LfF | 97.20 | 11.60 | 18.40 | 63.20 |
| JTT | 95.90 | 8.10 | 13.30 | 40.10 |
| EIIL | 95.50 | 4.20 | 24.70 | 44.90 |
| DebiAN | 98.00 | 14.90 | 10.50 | 69.00 |
| DDB-I (ours) | 86.39 ± 0.74 | 1.85 ± 3.21 | 0.52 ± 1.38 | 0.12 ± 1.56 |
| DDB-II (ours) | 98.56 ± 0.92 | 2.30 ± 0.60 | 11.10 ± 1.20 | 46.70 ± 2.42 |
Key findings
State-of-the-art performance
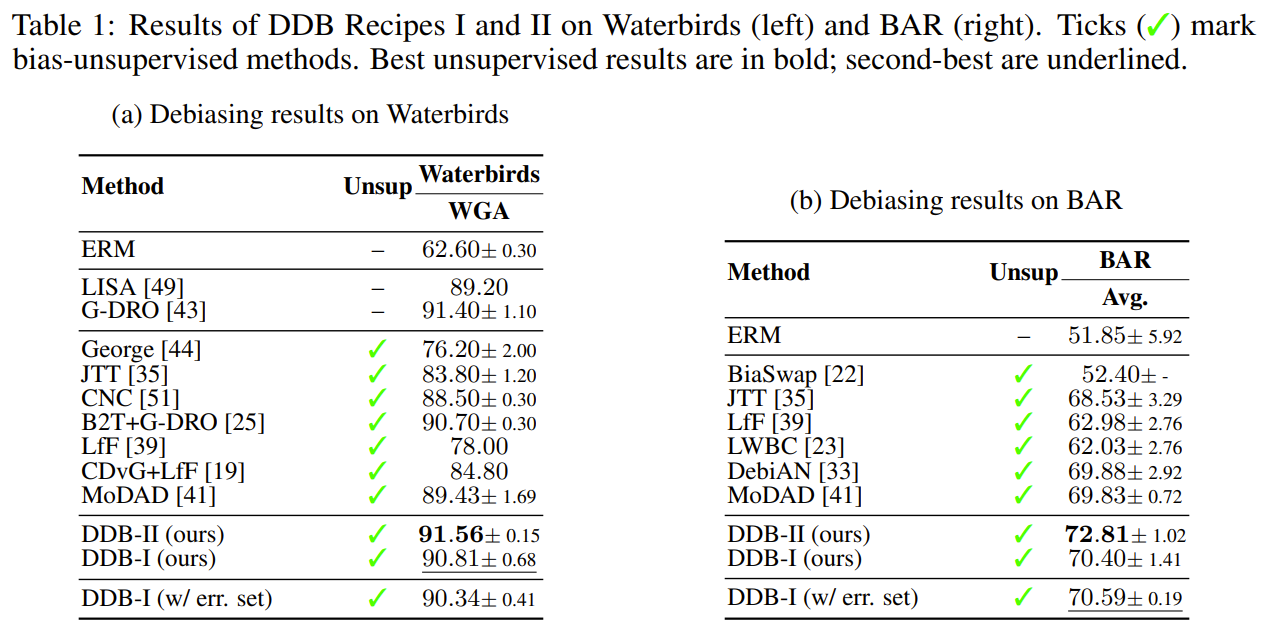
Both DDB recipes show state-of-the-art results across all benchmarks; on Waterbirds, DDB-II (91.56% worst-group accuracy) is above all unsupervised methods and the supervised GroupDRO (91.40%)
Synthetic data is crucial
On Waterbirds, a BA trained on real data memorized all bias-conflicting samples in 50 epochs (empty pseudo-label groups) and reached only 79.43% WGA when trained for one epoch (Recipe I); with Recipe II it gave 78.45%
Bias Amplifier data
All main results use 1,000 synthetic images per class; even 100 synthetic images are enough for good debiasing performance
Limited impact of CFG strength
On Waterbirds (Recipe I), WGA ranges from 87.85% to 90.81% for guidance strength w ∈ {0, 1, 2, 3, 5}, with the best result at w = 1
Bias identification
The BA identifies bias-aligned and bias-conflicting training samples with 89.00% accuracy on Waterbirds and 96.00% on BFFHQ
No degradation on unbiased data
On CIFAR-10, Recipe I gives 84.16% test accuracy vs. 83.26% for ERM with the same ResNet-18
Poster
Frequently asked questions
What is Diffusing DeBias?
Diffusing DeBias (DDB) is an unsupervised model debiasing method for image classification, published at NeurIPS 2025. It trains a class-conditional diffusion model with classifier-free guidance on the biased training set and samples synthetic bias-aligned images, which fully replace the real training set for training a Bias Amplifier. Because the Bias Amplifier never sees real data, it cannot memorize the few bias-conflicting training samples. Code is available at https://github.com/Malga-Vision/DiffusingDeBias.
How is the Bias Amplifier used for debiasing?
Diffusing DeBias is a plug-in for two recipes. Recipe I (two-step) takes the training samples misclassified by the Bias Amplifier, filtered with a per-sample loss heuristic, as pseudo-groups for GroupDRO. Recipe II (end-to-end) uses the Bias Amplifier losses to reweight training samples in an LfF-style scheme. All main results train the Bias Amplifier on 1000 synthetic images per class.
Which datasets is Diffusing DeBias evaluated on?
Diffusing DeBias is evaluated on Waterbirds, BFFHQ (Biased Flickr-Faces-HQ), BAR (Biased Action Recognition), ImageNet-9 with testing on ImageNet-A, and UrbanCars, which contains multiple shortcuts (background and co-occurring object). Results are averaged over three independent runs.
How well does Diffusing DeBias perform?
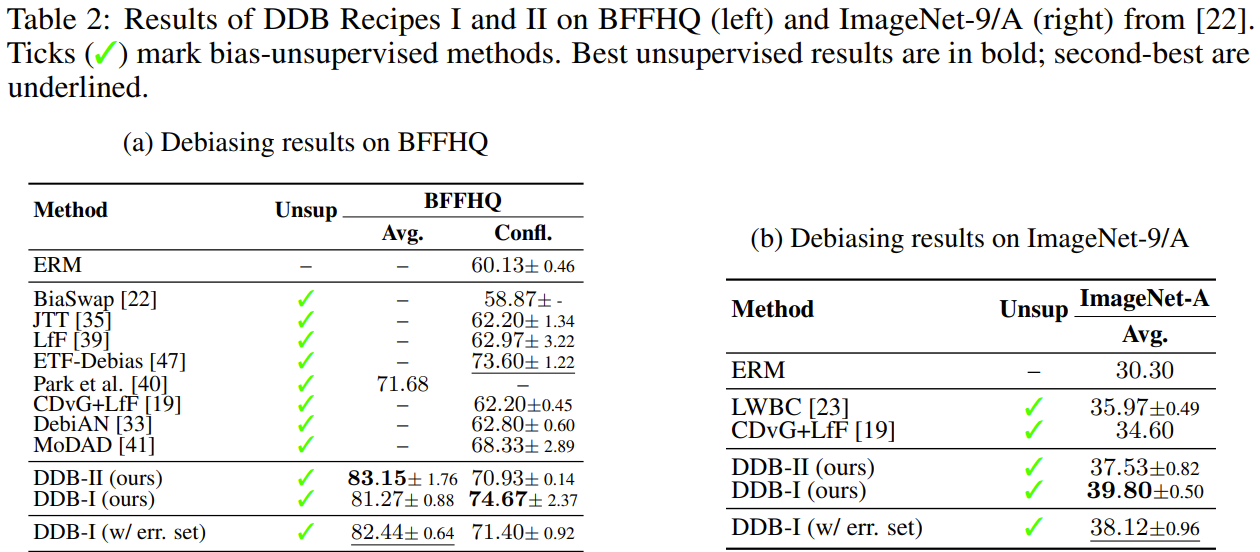
On Waterbirds, DDB-II reaches 91.56% worst-group accuracy, above all unsupervised methods and the supervised GroupDRO (91.40%). On BAR, DDB-II reaches 72.81% average accuracy, 2.93 points above DebiAN. On BFFHQ, DDB-I reaches 74.67% bias-conflicting accuracy against 73.60% for ETF-Debias, and on ImageNet-A DDB-I reaches 39.80% average accuracy.
Why train the Bias Amplifier on synthetic data instead of real data?
In the NeurIPS 2025 paper, a Bias Amplifier trained on the real Waterbirds training set for 50 epochs memorized all bias-conflicting samples, leaving empty pseudo-groups; training it for one epoch gave only 79.43% worst-group accuracy with Recipe I, and a frozen Bias Amplifier trained on real data gave 78.45% with Recipe II. Diffusion-generated images were rated bias-aligned in 98.35% (Waterbirds), 99.20% (BAR) and 99.70% (BFFHQ) of cases. On unbiased CIFAR-10, Diffusing DeBias does not hurt accuracy (84.16% vs. 83.26% for ERM).
Citation
@inproceedings{ciranni2025diffusing,
  title={Diffusing DeBias: Synthetic Bias Amplification for Model Debiasing},
  author={Ciranni, Massimiliano and Pastore, Vito Paolo and Di Via, Roberto and
          Tartaglione, Enzo and Odone, Francesca and Murino, Vittorio},
  booktitle={Advances in Neural Information Processing Systems},
  editor={D. Belgrave and C. Zhang and H. Lin and R. Pascanu and P. Koniusz and M. Ghassemi and N. Chen},
  volume={38},
  pages={116778--116805},
  publisher={Curran Associates, Inc.},
  doi={10.52202/085713-3893},
  year={2025}
}